Status line
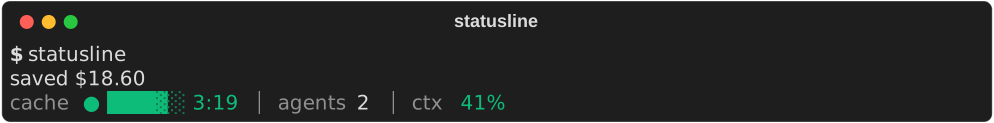
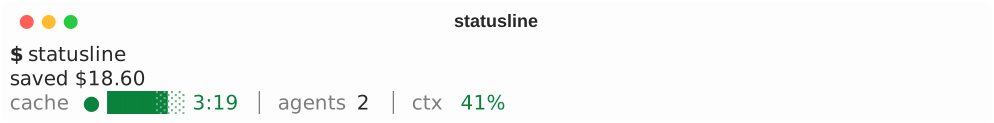
The status line sits under the prompt and answers two questions all the time: how much am I saving, and is my cache about to cost me? It shows nothing in a project that is not routed through the proxy.
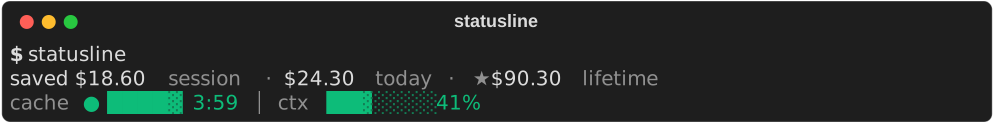
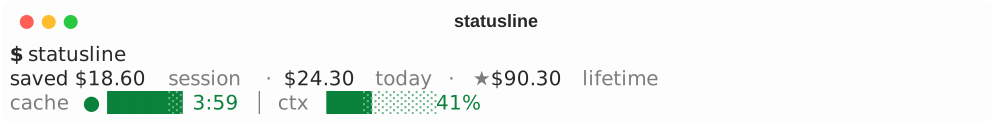
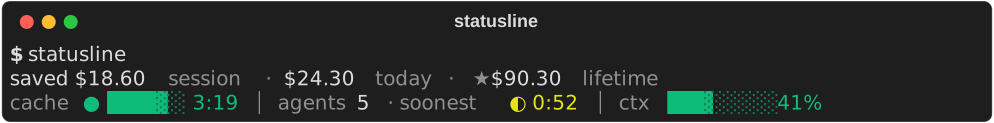
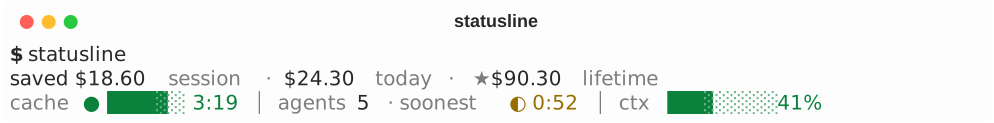
The first line is money, the second is the cache clock, the sub-agents, the context bar and at most one hint:
saved $0.31 session · $4.20 today · ★ $212.40 lifetime
cache ● █████░ 3:57 │ agents 2 · soonest ◐ 0:51 │ ctx ███░░░░░ 41%
What each piece means
| Piece | Meaning |
|---|---|
saved $0.31 session |
Saved this session: modelled against the same requests without the proxy, at your gateway's prices, net of the proxy's own spend. |
$4.20 today |
The same measure since local midnight. |
★ $212.40 lifetime |
The same measure over everything this proxy has recorded. |
cache ● █████░ 3:57 |
A bar that drains as the prompt cache approaches expiry, and the clock. Time is measured from the end of the last response. |
↻ after the clock |
The last touch of the cache was a keep-alive ping. |
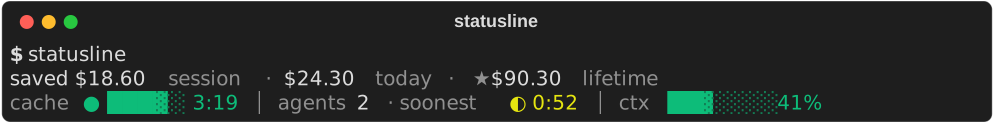
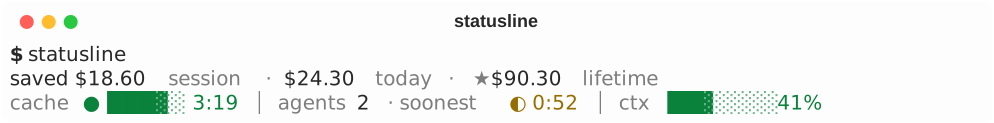
agents 2 · soonest ◐ 0:51 |
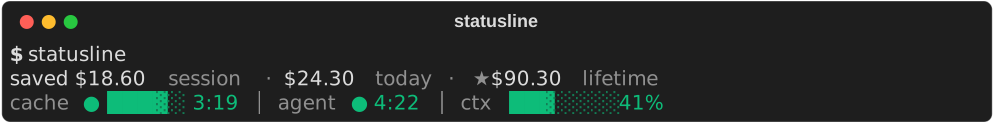
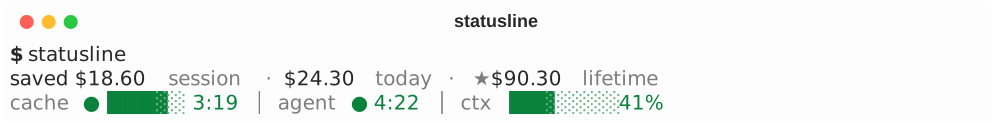
Running sub-agents: the count and the clock of the one whose cache expires first (a single agent shows its own clock, as agent ● 4:21). Each has its own cache. Finished (cold) ones are not shown. |
ctx ███░░░░░ 41% |
How full you are, as a share of the model's context limit. |
▸ hint |
At most one thing worth acting on, dollars first. |
▲ update v0.3.2 |
A newer proxy release is waiting; shown first so it cannot scroll off. |
The cache clock
| State | Looks like | Rule |
|---|---|---|
| Warm | green ● |
more than 60 s left (a fifth of the lifetime on the 1 h tier) |
| Expiring | amber ◐ |
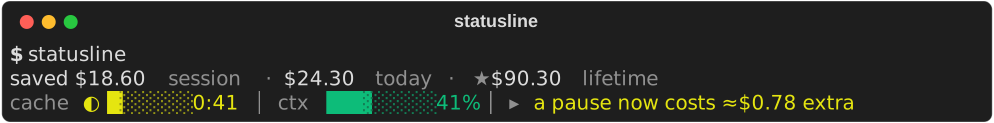
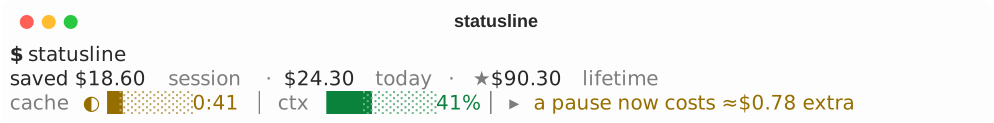
60 s to 15 s left; the hint prices what a pause would cost |
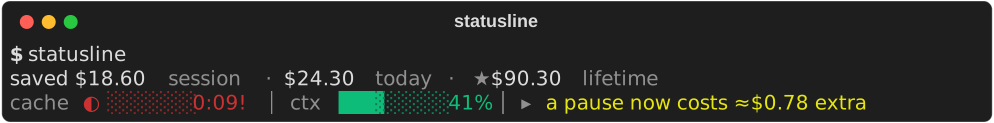
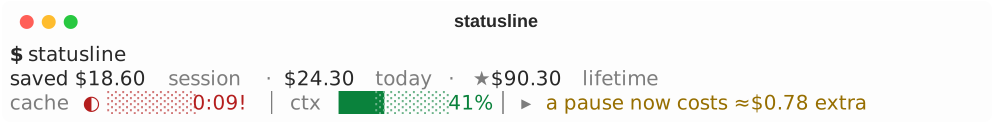
| Critical | red ◐ 0:09! |
the last 15 s |
| Cold | red ○ cold 1:15 |
expired; counts up how long it has been cold |
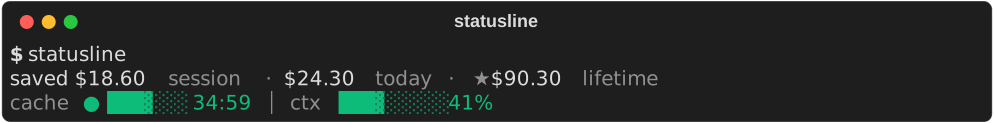
The bar drains over the cache's own lifetime: 5 minutes, or 1 hour on the 1 h tier.
Every state
Warm: green, seconds ticking down
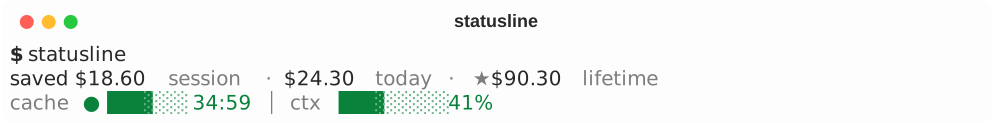
Warm on the 1 h cache tier
The bar rescales to the tier's lifetime.
Expiring: amber, with what a pause would cost
Critical: red, last 15 seconds, marked !
Cold: counts up how long it has been cold
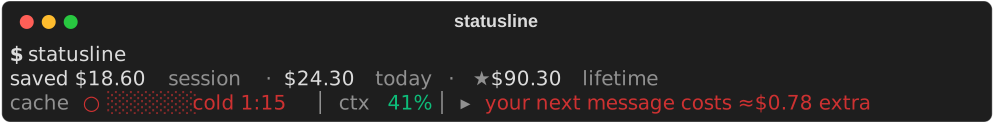
Keep-alive ping in place: ↻
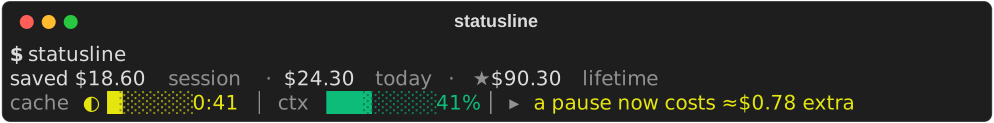
Sub-agents
One running sub-agent, then several (the count and the one expiring soonest), then five.
Model changed while the cache is warm
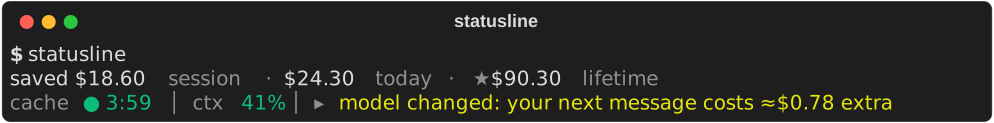
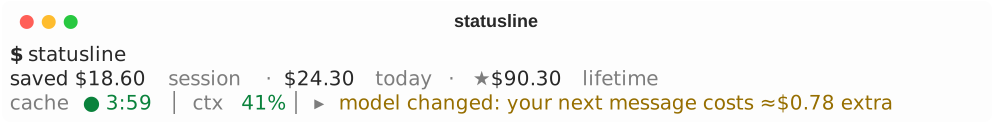
Switching model rewrites the cache, so the hint says so before you send.
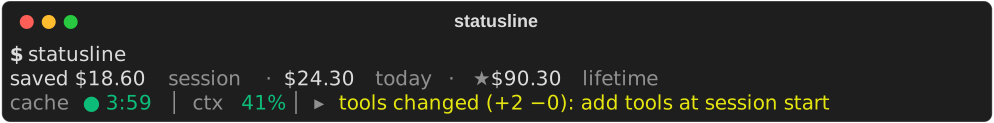
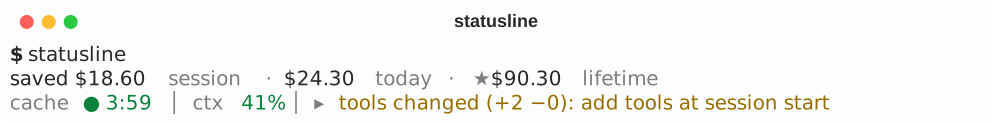
Tool set changed
From Claude Code's own miss report, when it is under two minutes old.
Proxy offline


Refused is cg ✕ proxy offline. A slow proxy shows cg: stats loading…, then the last numbers with ⏳. Hung for ten minutes shows cg? not responding.
Narrow terminals and the worst case
At 80 columns, with the cache cold, five sub-agents and a hint:
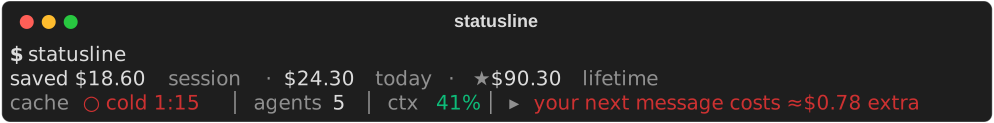
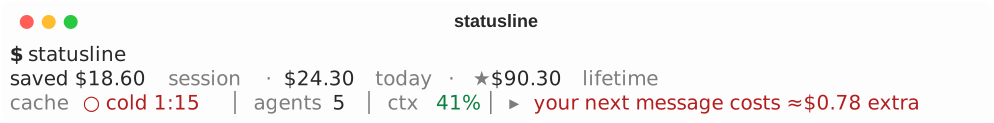
At 40 columns the line sheds, in order: tools, latency, spend, the update marker, the long hint form, then the agents shrink to a count, then the saved label and the context bar. The cache clock is shortened last.
Layouts
| Layout | Shows |
|---|---|
minimal |
one line: saved, cache, hint |
balanced (default) |
update, saved, cache, agents, context, hint |
detailed |
balanced plus spent $4.10 · $2.73/h · up 1h30m (the rate appears after 5 minutes), a slow-upstream note (only when upstream averages 3 s or more) and the least-used tool or skill |


Switch without editing settings, and keep the choice across renders:
auto forgets the choice. A remembered layout wins over the flag in the installed command. To change the installed command instead, re-run /context-guru:statusline with --layout=minimal|balanced|detailed. Hide or show single elements with --hide=a,b and --show=a,b (update save spend cache agents ctx hint latency tools ka), or the environment variables CG_STATUSLINE_LAYOUT, CG_STATUSLINE_HIDE, CG_STATUSLINE_SHOW and CG_STATUSLINE_COLUMNS.
Modes
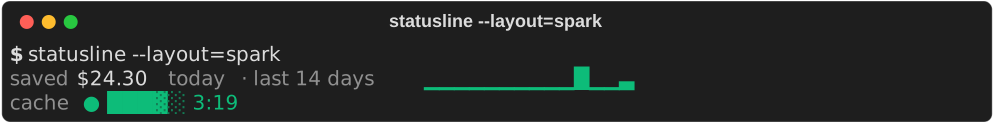
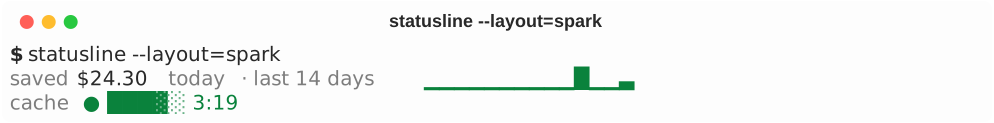
Five more layouts each answer one question on the second line, next to the cache clock. Choose one with --layout=<name> in the installed command, or remember it with statusline.py --set-layout=<name> (--set-layout=auto goes back to the default).
| Layout | The question | What it shows |
|---|---|---|
spark |
How much have I saved lately? | saved $4.20 today · last 14 days ▂▄▅…: today's saving and a 14-day sparkline by your local calendar day; the rightmost cell is today |
strip |
Are my cache hits holding? | The last 20 requests as ■ hit, ▨ partial, ✖ miss (oldest on the left), and the dollars misses cost today ($1.40 lost today); from 100 columns a key is added |
heat |
When do I lose cache? | misses/hour 0h … 24h $1.40 lost today: ░▒▓█ mean more misses in that hour, blank none, · hours not yet reached; the dollars are the whole day |
fill |
How full is my context, and with what? | A stacked bar: ▒ always loaded, █ conversation, ░ free; the percent and, when it is filling, the time to full. At 100 columns or more, a legend with the two shares and what a miss now would cost |
watch |
Which sub-agent caches are about to lapse? | Line 1 the saved figure and the main clock; line 2 agent caches (2) ████ 4:30 █░░░ 0:50: one mini-bar per running sub-agent in id order, up to 4, then +N more |
All five show the cache clock but have no hint slot.
spark
strip
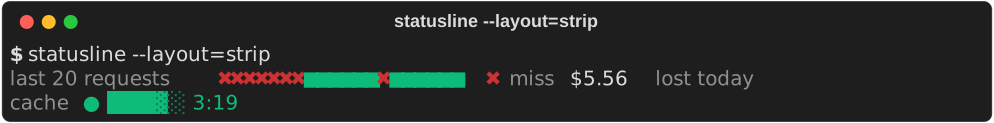
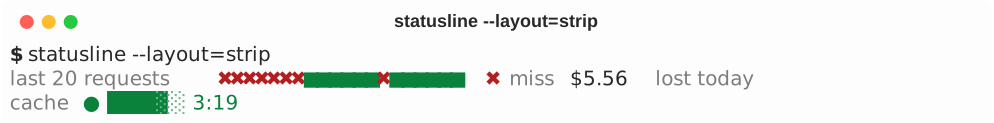
At 120 columns:


heat
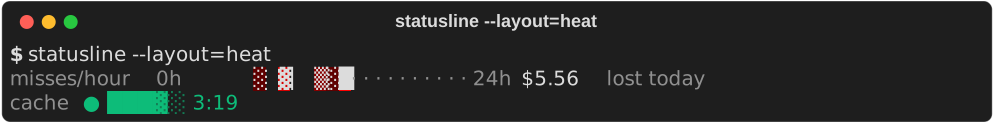
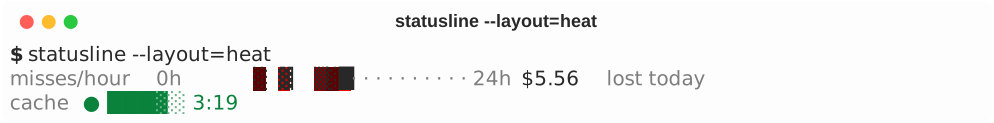
fill
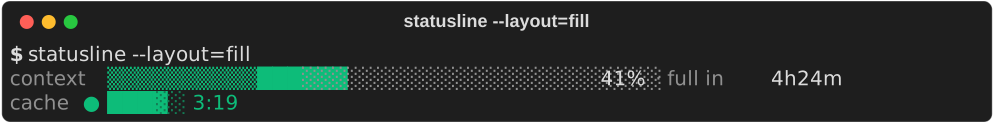
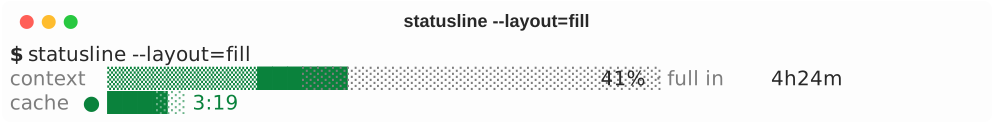
With room for the legend (120 columns):


watch
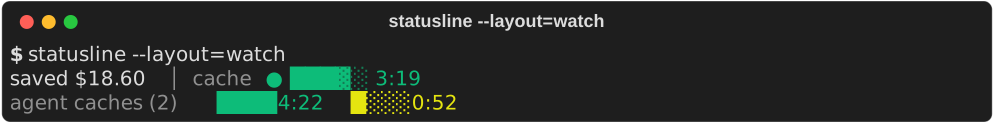
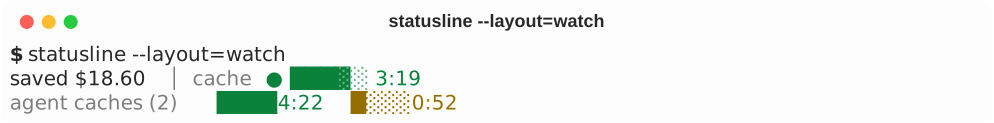
These layouts draw with the same renderer as the terminal views. NO_COLOR removes the colour, and CG_ASCII=1 swaps the glyphs for plain characters (o hit, ~ partial, X miss, #, = and - for bars). That ASCII switch exists for these layouts only; the default layouts have none. Their data is cached (series and spend for 2 minutes, requests for 4 seconds) and a render never waits for it.
Refresh and the one-second clock
Claude Code redraws the status line on every message and, if you ask, on a timer. The installer writes "refreshInterval": 1 next to the command, so the clock ticks every second (the minimum Claude Code accepts). A value you set yourself is kept when the status line is re-installed, so an install made earlier with a longer interval keeps it. To get the one-second clock on an existing install, set it by hand in the settings file that holds the status line:
and start a new session. Older Claude Code versions ignore the key and redraw only on events. The clock is arithmetic on a timestamp the proxy supplies, so a redraw needs no new network read. A render takes about 55 ms warm and 90 ms on a cold cache. The cost is one short process per second per open session. If that matters, set a larger refreshInterval (for example 5); the clock then moves every 5 seconds.
Render time
Every layout returns in about 0.4 s at worst, Python start-up included (the slowest run in the table took 0.43 s). The render has a 0.36 s budget. Only the proxy's totals (/api/stats?lean=1) are waited for, and the cache state is read in parallel under the same deadline. Everything else (day and lifetime totals, series, spend, requests) comes from a disk cache that a detached background process refreshes, one per 30 seconds. A timeout shows the last numbers with ⏳, never "proxy offline".
Measured on this host, which is loaded and shared with production: 50 runs per cell, wall milliseconds, median / 95th percentile / maximum. "Slow" is a server that sleeps 5 seconds on every request.
| layout | healthy, warm cache | healthy, cold cache | slow proxy | proxy down |
|---|---|---|---|---|
| minimal | 53 / 59 / 64 | 89 / 97 / 97 | 389 / 398 / 399 | 92 / 98 / 106 |
| balanced | 51 / 60 / 66 | 89 / 104 / 133 | 390 / 397 / 401 | 94 / 105 / 110 |
| detailed | 57 / 66 / 70 | 93 / 103 / 110 | 389 / 395 / 398 | 91 / 101 / 104 |
| spark | 55 / 64 / 64 | 90 / 102 / 108 | 389 / 393 / 396 | 92 / 104 / 127 |
| strip | 54 / 58 / 61 | 89 / 97 / 103 | 391 / 399 / 406 | 89 / 111 / 125 |
| heat | 55 / 60 / 67 | 90 / 99 / 101 | 391 / 410 / 425 | 92 / 111 / 116 |
| fill | 54 / 57 / 61 | 85 / 94 / 94 | 390 / 408 / 427 | 81 / 92 / 120 |
| watch | 55 / 59 / 63 | 91 / 101 / 104 | 391 / 412 / 416 | 91 / 97 / 99 |
The same harness on the status line before this work:
| layout | healthy, warm cache | healthy, cold cache | slow proxy | proxy down |
|---|---|---|---|---|
| minimal | 42 / 59 / 63 | 80 / 89 / 93 | 682 / 691 / 692 | 76 / 90 / 91 |
| balanced | 44 / 53 / 54 | 80 / 91 / 99 | 679 / 729 / 751 | 75 / 82 / 86 |
| detailed | 45 / 52 / 60 | 79 / 89 / 98 | 678 / 703 / 713 | 83 / 126 / 146 |
The slow-proxy case went from about 680 ms to about 390 ms. Healthy renders are about 10 ms slower than before, from the extra elements (agents, spend).
Colour and plain terminals
Colours are the basic ANSI set plus dim, so they follow your terminal theme on light and dark backgrounds. NO_COLOR=1 or TERM=dumb removes the colour; the clock, bar and symbols still carry the state. The default layouts have no ASCII mode: their bars and symbols are Unicode (the modes can switch to ASCII with CG_ASCII=1). --layout=minimal keeps to one short line.
Turn it on, off, or change it
/context-guru:statusline installs it (the install also does this by default), changes the layout, or turns it off with settings.py off, which restores whatever status line you had before. It never sends a keep-alive ping; it only reads.